Theo Schmidt · 8 October 2026
Implementing Adaptive Search Algorithms to Improve Information Retrieval in Collaborative Productivity Environments
Collaborative productivity environments depend on quick access to shared documents, task lists, and communication threads, and adaptive search algorithms address this need by adjusting results based on patterns in user behavior and context within team workspaces. These systems analyze past queries, file interactions, and group dynamics to refine rankings without requiring manual configuration each time a new project begins. Data from industry reports shows that organizations using such tools experience measurable gains in locating relevant materials across distributed teams.
Core Mechanisms Behind Adaptive Search
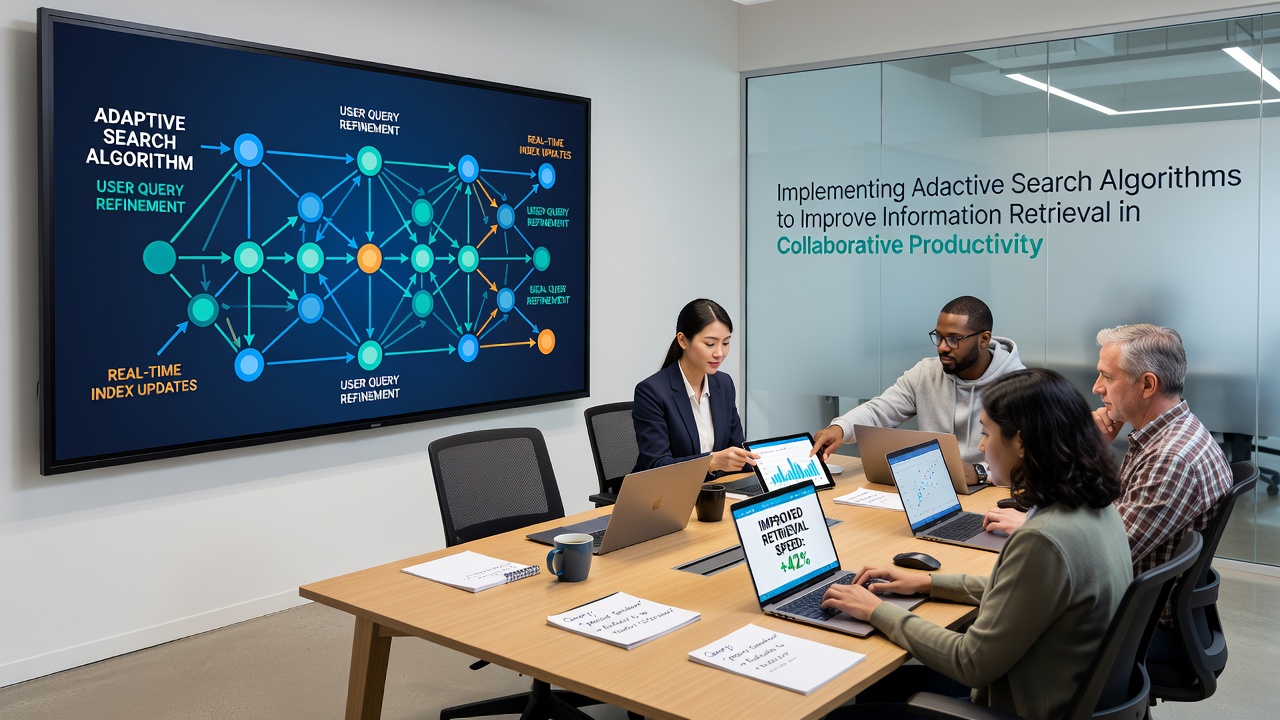
Adaptive search relies on machine learning models that update continuously as team members interact with the platform, and these models incorporate signals like click-through rates, dwell time on documents, and collaboration frequency among specific users. Researchers at institutions including the University of Toronto have documented how context-aware weighting improves precision when multiple people contribute to the same knowledge base. teh process starts with baseline retrieval methods such as vector embeddings for semantic similarity, then layers on personalization factors that shift according to project phase or team role. As of October 2026, several platforms report integration of real-time feedback loops that recalibrate results within seconds of new edits appearing in shared repositories.
Deployment in Team-Based Workflows
Teams working across time zones benefit when search adapts to individual preferences while preserving consistency for the group, and this balance comes from federated learning approaches that keep sensitive interaction data localized. Observers note that implementation typically begins with indexing all content types including notes, spreadsheets, and chat histories, followed by training on anonymized usage logs. One study revealed that companies adopting these methods reduced average time spent locating files by up to 30 percent in the first quarter after rollout. External validation appears in reports from the Commonwealth Scientific and Industrial Research Organisation, which examined cross-platform retrieval in multinational settings.
Technical Integration Steps
Development teams follow a sequence that includes data collection, model selection, and ongoing evaluation, yet the sequence allows flexibility when platforms already contain established APIs. Initial setup involves mapping user roles to relevance signals, after which algorithms test variations through A/B frameworks embedded in the live environment. Engineers monitor metrics such as mean reciprocal rank and normalized discounted cumulative gain to confirm improvements, and adjustments occur automatically when thresholds are crossed. Integration with existing productivity suites requires attention to latency, because delays in result delivery can offset gains from smarter ranking.
Security considerations enter at the model training stage, since collaborative spaces often contain access-controlled materials that algorithms must respect during ranking. Access policies translate into feature constraints that prevent unauthorized documents from surfacing even when semantic matches appear strong. Data indicates that platforms enforcing these constraints maintain compliance while still delivering adaptive benefits to permitted users.
Observed Outcomes Across Organizations
Case examples from software firms and research labs illustrate consistent patterns, including faster onboarding for new members who rely on search to navigate legacy project archives. Metrics collected after deployment show increases in both recall for long-tail queries and satisfaction scores from repeated users. The ACM SIGIR community has tracked similar trends through conference proceedings that cover enterprise deployments. Another source, the National Institute of Standards and Technology, provides evaluation frameworks that organizations apply to verify algorithm performance under collaborative loads.
Challenges surface when query distributions change abruptly, such as during mergers or major product launches, and adaptive systems handle these shifts through incremental retraining rather than full resets. Teams that maintain diverse usage data see more robust adaptation, whereas narrow interaction patterns can lead to overly specialized results that miss broader needs.
Conclusion
Adaptive search algorithms continue to evolve alongside productivity platforms, and their value lies in processing interaction data to surface relevant information across shared environments. Organizations tracking performance metrics through October 2026 and beyond gain clearer pictures of how these systems scale with team growth and content volume. Continued refinement depends on combining established retrieval techniques with fresh behavioral signals while preserving access controls and response speed.